I was reading this article from GitHub about how they use eBPF to improve reliability and safety when deploying to prevent circular dependencies. In short, what happens when the tools you need to fix Github unexpectedly also depend on GitHub itself!
The downsides of dogfooding
Github uses MySQL as a cornerstone of their infra, and although I'm sure one can find PostgreSQL on their stack, they have been using MySQL almost from their beginnings. Now, let's imagine that GitHub experiences a serious incident involving MySQL. To solve it, the engineers need to deploy a change related to the configuration in those affected servers, and for these cases they have internal tooling and scripts. Something that conceptually would look like this: bash deploy-mysql-config.sh .
That script can do many things: copy a new configuration, validate files, install a dependency, run some tool, reboot a service, make sure that MySQL is healthy, etc. The issue appears when any of these tools has a hidden GitHub.com dependency.
In normal conditions the deploy would move forward and it wouldn't be an issue but, if GitHub is down, then the deploy is stuck because it is trying to download a dependency that isn't reachable at that moment.
MySQL fails
    ↓
GitHub.com starts to fail
    ↓
Need to deploy a change to fix MySQL
    ↓
The deploy tool tries to access GitHub.com
    ↓
Github doesn't work because MySQL is down
    ↓
We cannot run the tool that we need to fix MySQL... and so on
And that's how we get to a circular dependency, where the infrastructure needed to recover GitHub relies on GitHub itself. And discovering something like this when there's an outage, well... not ideal.
The solution here is forcing recovery tools to work always without having access to GitHub. Now, an engineer can investigate calmly -and before an outage happens- why a certain tool needs access to GitHub and search for an alternative solution like packaging the binary locally, internal mirroring, disable update checking or changing the architecture of the deploy. Then, when a real incident occurs recovering the infra isn't blocked by other parts of the app being down.
This approach is very similar to fault injection or chaos engineering tests: introducing on purpose a restriction to make sure the system knows how to survive it.
An eBP what?
In order to understand eBPF we need to separate two worlds that live inside Linux. On one side, we have the userspace, where all the normal programs run, see Rails, nginx, curl, etc. And underneath we have the Linux kernel that controls things like processes, memory, sockets and much more.
What does eBPF do? It allows executing small programs inside the Linux kernel and hook them into specific system events. You could execute code when a new network connection is created, a packet is passed or a specific kernel event happens. And the magic part here is that it allows you to make certain parts of the Kernel programmable without needing to recompile it or write a traditional kernel module.
Usually eBPF is used for these three things: Observability, networking and security.
- Observability: We can use it to debug in the case that our Rails app starts to slow down and we want to know why. For example, when opening a file we can hook an eBPF program to the write() syscall and then measure the time, count the calls or know which process was. Usually with eBPF you can answer questions like "Who is connecting to this IP", "How long are TCP connections taking" or "Where is this process spending CPU time?". And all of this without modifying Rails, Nginx or curl. That's why it is so used in profiling and tracing.
- Networking: This is where eBPF shines since almost al network traffic goes through the kernel so, based on the hook kind, you can decide to allow, drop, redirect or choose another destination. That's why it is used for firewalls, DDoS filtering, load balancing, etc
- Security: Here we have the GitHub example, those cases where you want to filter which processes have access to certain endpoints.
One important concept that the GitHub team uses is BPF maps. It wouldn't make sense to add 50.000 IPs directly into the eBPF program. That's where BPF maps come to the rescue. These are data structures that can be shared between eBPF and normal programs that live in the userspace. So while the higher level program handles the DNS, policy management or similar, the eBPF just does lookups in the IP map, quick and simple.
What about UFW?
We could definitely do a ufw deny out to <GitHub IP> or similar rule with iptables or nftables. And it is important to clarify that these tools also end applying those rules within the Linux kernel, these are just a higher level abstractions to configure the firewall rules.
The issue with this approach is that GitHub doesn't want to fully lock that server from accessing its servers, they just want the deployment tool and its processes to be prevented from accessing their services while the rest of the server could definitely rely on some GitHub hosted package. And here is where cgroups come into play.
Cgroups, an abbreviation of control groups, is a feature that allows us to cluster processes within Linux and apply rules that are unique them. For example, containers like Docker use cgroups extensively to implement resource restrictions and access limits to CPU and memory. Or, in this case, the GitHub team decided to pair the power of cgroups with eBPF. That way you can have MySQL, backups or monitoring processes using normal uncapped networking, while a deployment group that holds the deploy.sh + curl + helper runs its networking through eBPF where any github.com call gets blocked. We are applying a networking policy, not for the whole machine, but for a concrete process tree.
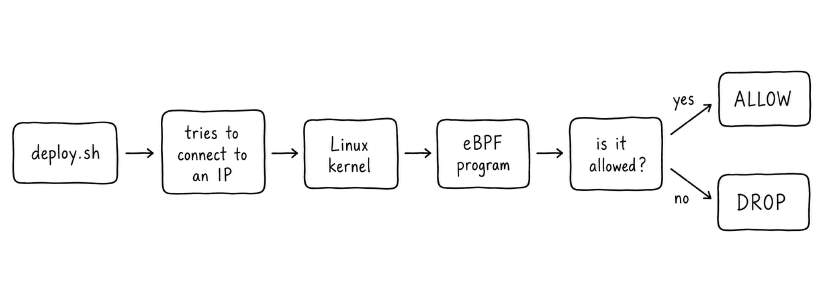
Summary
Although I started reading this article because I didn't know what this eBPF was and I wanted to understand why it was so important, the most interesting idea in this read isn't this feature, but what's behind the though of using it:
What things are we assuming that will have to work when everything else is down?
We usually don't worry or even think about those processes that are working smoothly until the moment they stop working and, in some cases like this one where it is a deploy service, we need to be safeguard it and not just test the happy path. eBPF is just an extremely precise way of doing this: in the kernel, over an chosen group of processes and without affecting the rest of the machine.
Godspeed!